Tracing, accounting, debugging, and diagnostics
These mechanisms answer different questions. An event trace records selected transitions over time; a performance sample captures selected state at a trigger; an accounting counter accumulates usage; a stackshot captures structured task/thread state; a debugger inspects a live or saved kernel image. Confusing these roles leads to incorrect conclusions about missing events or apparently inconsistent totals.
For detailed artifact lifetimes, continue with stackshot capture and kcdata, corpses and process core files, and ARM64 panic coordination and records. These trace admission, storage, collection, publication, partial failure and cleanup; KDP protocol and kernel-core transport are outside this expansion.
For log production and delivery, read kernel logging and Firehose: format encoding, small allocation arenas, per-CPU retry queues, chunk publication, live-stream reservations/cache, read-only mappings and msgbuf replay have distinct completion and loss rules.
Map the question to the mechanism
Sanitizer runtime and reporting traces classic shadow bytes, software TBI tags, allocator hooks, quarantine/fake stacks and KASAN/UBSAN reporting decisions. Coverage instrumentation lifecycle follows compiler callbacks, KSANCOV modes and mapped buffers, current-thread attachment, record ordering and detach/close.
| Question | Mechanism | Source entry |
|---|---|---|
| In what order did selected events occur? | kdebug event records | kdebug.c, kdebug.h |
| What ran at a sampling trigger? | kperf actions and samplers | action.c, kptimer.c |
| How much CPU time or counter usage accumulated? | Recount, with hardware-counter support | recount.h, recount.c |
| What device values or state residency did a driver publish? | IOReport channels, elements and samples | Reporter implementation and sampling protocol |
| Which submitted device work is associated with a thread group? | IOPerfControl client tokens and contexts | Performance-control ownership and completion |
| What were tasks and threads doing together? | Stackshot | BSD entry, collector |
| What objects and references exist in a stopped kernel? | LLDB macros and kernel debug data | tools/lldbmacros |
| Where did a log record go, and why is it missing from one consumer? | OSLog, Firehose handoff, live stream and msgbuf | Producer, buffering and readout mechanisms |
| Where did memory misuse or undefined behavior occur? | Configured sanitizer instrumentation | san/memory |
| Which instrumented paths ran? | Coverage instrumentation | san/coverage |
ktrace controls; kdebug records
The Kdebug storage and readout companion follows record reservation, storage reuse, timestamp merging, loss reporting and partial output through to reset. It distinguishes these trace records from the formatted/binary logging paths.
The control plane in kern_ktrace.c manages a mutex, off/foreground/background state, active subsystem mask, and owner identity. It uses a process unique identifier as well as a PID: ktrace_ownership_maintenance() checks that a found PID still names the owner instead of trusting a recycled PID. ktrace_configure() permits the existing owner, controls foreground/background takeover, and rejects conflicting owners. Access checks are part of this path; development/debug entitlement behavior is guarded separately from the superuser check.
The event path is in kdebug.c. A typical kernel call follows:
kernel_debug(debugid, arguments)
  -> kernel_debug_internal(..., current thread ID, ...)
     -> _write_trace_record(...)
        -> check emission/debugid/process filters
        -> disable preemption
        -> select current CPU and reserve timestamped record
        -> fill debugid, arguments, thread identity, CPU
        -> enable preemption
        -> optional kperf callback
     -> consider reader wakeup threshold
_next_timestamped_record() atomically reserves an index in a storage unit and obtains a timestamp in the reservation loop. Preemption control keeps the producer associated with the selected CPU while filling its record; it is not a blanket lock on all kernel activity. The payload's meaning comes from the event code and its instrumentation site, not from kd_buf alone. Search trace_codes and the emitting call site together.
When interpreting a trace, check whether the event was compiled in, enabled, filtered, and retained by the chosen buffer mode. Absence of an event is not by itself proof that the underlying operation never happened. The controls and write path above explain several ways it can be absent.
kperf: trigger, action, sample
kperf_sample() checks the action ID, applies its PID filter, obtains its sampler mask and stack-depth settings, then invokes kperf_sample_internal(). An action therefore specifies what to collect; a trigger determines when to collect it.
The timer path kptimer_sample_curcpu() builds a context with the current thread, task, PID, trigger type, and timer ID, then calls kperf_sample() with flags that can defer user sampling. The kdebug-triggered path kperf_kdebug_handler() checks its trigger and constructs a similar context. Read individual samplers for collection constraints; a timer callback does not imply that arbitrary user-stack walking is safe synchronously.
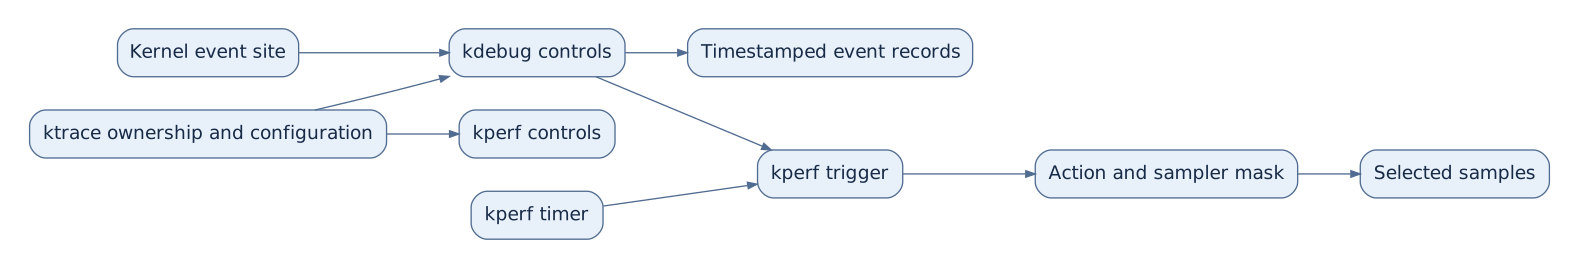
Mermaid source
flowchart LR
    KT[ktrace ownership and configuration] --> KD[kdebug controls]
    KT --> KP[kperf controls]
    E[Kernel event site] --> KD
    KD --> R[Timestamped event records]
    KD --> TR[kperf trigger]
    TI[kperf timer] --> TR
    TR --> A[Action and sampler mask]
    A --> S[Selected samples]
Hardware counter management has its own implementation, including kpc_common.c, cpc.c, and architecture backends. The existing CPU-counter guide is useful context. Sampling configuration and always-accumulated accounting should be read separately.
Recount: accounting tied to execution transitions
recount.h defines topology domains: system-wide, per CPU, and per CPU kind. A recount_plan selects granularity. A recount_track contains rt_sync and rt_usage; usage includes per-execution-level metrics with rm_time_mach, and configuration-dependent rm_instructions, rm_cycles, and energy state.
At recount_switch_thread(), the current snapshot is subtracted from the previous per-CPU snapshot. recount_absorb_snap() attributes the delta to the outgoing thread/task and processor, with configuration-dependent work-interval attribution, then the previous snapshot is replaced. User/kernel transition functions update attribution at finer boundaries on supported paths. Energy arrives through a separate update path and is not interchangeable with time sampled at every boundary.
Readers need related counters to describe a consistent interval. recount_read_track() reads a sequence counter, copies the usage, and retries if a writer changed it. The updater publishes changes through the corresponding sequence-lock helpers. This differs from simply taking a mutex around every user of the statistics. It also does not remove the writer-side execution/topology assumptions documented in the header.
The existing Recount guide maps counters to task/thread/process APIs and LLDB commands. Prefer the current structure definition for exact field names: documentation prose and source can evolve at different speeds. Recount tracks are an example of why a structure's protection model matters as much as its field list.
Stackshot and kcdata
The BSD stack_snapshot_with_config() validates permissions, configuration version and size, copies the user configuration, calls kern_stack_snapshot_internal(), and translates the kernel return code. Entitlement reporting/refusal is conditional in this path; it is more precise to read that logic than to describe every configuration as having the same gate.
The collector in kern_stackshot.c coordinates capture state and output. stackshot_trap() enters DebuggerTrapWithState(DBOP_STACKSHOT, ...); on x86-64 it also excludes an overlapping multiprocessor rendezvous because both mechanisms coordinate CPUs. The file contains configuration-dependent collection paths, including multithreaded collection. See the original multithreaded stackshot guide before treating a historical stop-the-world diagram as universal.
Stackshot can describe task/thread state from many subsystems in kcdata, a chunked format. kcdata_item has a type, payload size, flags, and payload; items are aligned to 16-byte boundaries. Container markers group records, and type descriptions allow consumers to interpret structured data. Allocation and append helpers live in kern_cdata.c, including kcdata_memory_alloc_init() and kcdata_get_memory_addr().
libkdd is the user-side parser library, not another kernel scheduler or tracing engine. Its kdd.h exposes type descriptions and parsing into Foundation objects. tools/lldbmacros/kcdata.py is another useful decoding reference. The format lets output carry optional records without forcing every consumer to share the exact in-kernel structure layout.
Debugger navigation
Use symbols and structure definitions matching the image being inspected. The LLDB README describes loading the macros with a live connection or a core file; some examples in it are historical. For command availability and syntax in this checkout, use the registered command and its local help.
| Objects | Commands present in this tree | Definition |
|---|---|---|
| Tasks, processes, threads, stacks | showtask, showproc, showalltasks, showallthreads, showallstacks |
process.py |
| Processors and scheduling | showallprocessors |
scheduler.py |
| Zones and memory | zprint and memory inspection helpers |
memory.py |
| Event queues | showallkqueues |
kevent.py |
| IOKit objects | showobject and registry helpers |
ioreg.py |
| Extensions | showallkmods |
kext.py |
| CPU accounting | recount subcommands |
recount.py |
These are navigation starting points, not commands executed during this review. A debugger can display a pointer even when the object's logical lifetime has ended; interpret it with the subsystem's reference and teardown rules.
Sysctl: a typed control tree with handler lifetimes
For concrete networking exporters, see Skywalk diagnostics, configuration and tests. It follows snapshot sizing, object protection, user copies and counter ownership rather than assuming that a sysctl read is a single atomic view of the datapath.
Sysctl exposes many subsystem counters and controls through a tree of named/numbered objects. sysctl_oid records the parent/link, number, kind/flags, name, handler, arguments, format, and reference count. sysctl_req holds the caller, input/output positions, lengths, and transfer functions; SYSCTL_IN and SYSCTL_OUT dispatch through those functions. A sysctl is therefore not necessarily a direct read of a global variable: a handler can validate input, calculate a result, or perform a subsystem operation.
sysctl_root() traverses under sysctl_geometry_lock, resolves numeric or canonical-name lookup, checks flags/access, snapshots the handler, and references a nonpermanent OID before releasing the tree lock. It can then call the MAC sysctl hook and invoke the handler without keeping the whole tree locked. Unregistration must wait for active references before the object can disappear. A separate sysctl_unlocked_node_lock serializes handler paths whose traversed nodes did not declare CTLFLAG_LOCKED; the flag should not be read as “the framework will hold my subsystem's own lock for me.” The handler still has its own state-protection contract.
userland_sysctl() retries EAGAIN after resetting request/output state. This is another example of a public entry point whose result depends on handler semantics, permissions, and concurrent state. When studying a particular control, find its SYSCTL_* registration, decode its flags, read the handler, and then follow the subsystem calls. This section reviewed the dispatch and lifetime path, not every registered control.
Other instrumentation and diagnostic paths
DTrace lives under bsd/dev/dtrace, with central dtrace_probe(), ioctl control, and initialization in dtrace.c, provider code, and Darwin adaptation in dtrace_glue.c. Its compilation is selected by config_dtrace in bsd/conf/files. The provider and action lifecycle companion follows DOF/DIF validation, ECB attachment, separate recording activation, ARM64 syscall probes and fault recovery, buffer publication/readout and synchronized teardown. It distinguishes a global probe ID from a consumer EPID and a successful action from successful userspace delivery; other providers and complete opcode/helper semantics remain outside that review.
Kernel logging includes libkern/os/log.c, firehose support, and BSD's message buffer/log implementation. Those are distinct paths from kdebug's numeric event records. The logging companion follows the locally implemented producer, encoding, retry, streaming and readout paths and identifies the missing central Firehose implementation. Panic/debug entry and core-dump infrastructure are under debug.c and osfmk/kdp; extensible panic records are described in extensible_paniclog.md.
san/conf/files shows which instrumentation components require configuration options. KASAN's common code in kasan.c connects poison/unpoison operations to configured backends; classic and tag-based implementations have separate files. UBSAN and coverage have separate runtimes. The presence of these files says nothing about whether an ordinary release image contains the instrumentation.
Sources inspected and limits
The ktrace ownership path, kdebug record path, kperf trigger/action entry, Recount structures/update/read path, BSD stackshot gate, stackshot trap, kcdata definitions, sysctl handler dispatch/lifetime, and listed debugger registrations were inspected directly. The companion chapters now expand selected stackshot, corpse, process-core and ARM64 panic mechanisms. The logging companion adds local producer/encoder/allocator/queue, chunk-inline, live-stream and msgbuf mechanisms; the central Firehose manager and userspace consumers remain external. The DTrace companion adds the common consumer lifecycle and selected ARM64 integration, while the sanitizer and coverage companions add selected backend, reporting, buffer and thread-attachment lifetimes. No live traces, counter measurements, debugger sessions, or sanitizer runs were collected.